Star Schema in Power BI Desktop-Here’s Why.
I clearly remember my struggle using the Power BI application for first few days, until I learned about data modelling, especially the Star Schema model architecture. Learning it improved my understanding of data and made me work competently with enhanced performance.
In Power BI, data is imported or injected from various sources like SQL server, excel or web applications and so on. Next, we choose the tables and their relationships based on the business requirements and constraints. This physical model exhibits how data is actually held in the database. This is referred to as a semantic layer, also known as semantic model which is a structured, logical layer that sits between raw data sources and reports. It centralizes logic, security, and data management, making it easier for both technical and non-technical users to build reports and dashboards reliably.
A data model is a visual representation of data elements such as tables, columns and rows that define their relationship and establishes rules about how the data is stored, structured and used in a system. It also acts as a blueprint or map for databases and applications to ensure data quality, consistency, and management. These models guide the users about data lifecycle, clarify what data is needed, how it is connected. Such design or blueprint of how database is structured is called a ‘schema’.

This is the simplest diagram of star schema design. It contains two different tables, namely, the ‘Fact table’, and the ‘Dimension table. In a typical star schema, the fact table resides in the center and is surrounded by multiple dimension tables. Another key point to mention, there can be more than one fact tables in a schema. The name Star Schema comes from the shape which resembles a star.
The fact table holds the metric values that can be measured or aggregated. i.e. numbers, sales, revenues, and quantity, whereas the dimension tables are the tables that describe the facts (tables). These contain the descriptive attributes of the fact tables. With the dimension table information, we can filter the data from the fact table/s. This information is sliceable. For example, when calculating the profit, - based on region, based on products or by category or by specific time frame. In this scenario, profit is exhibited in fact table, and it is filtered on separate dimension tables which contain the details of regions, products, or categories.
However, one must understand normalization before diving deep into start schema. Many a times data is presented in flat tables, which means the data is concentrated in one single file which involves a substantial number of columns and consequently into multiple rows, also known as wide tables. Normalization refers to breaking down this huge data file into small different multiple tables.
The figures below will ease understanding the concept better. The first big table is a flat table which houses all the data in one.
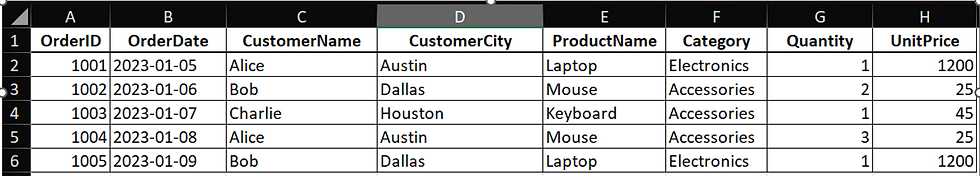
The table stores the customer’s name which gets repeated as the customer purchases different items. This practice can cause:
1. Larger data size
2. Slower performance
3. Harder to maintain
4. Inconsistent data
5. No reusability
To overcome these limitations, we break down the data into multiple but smaller tables.

Practicing this approach of normalized data will result in:
1. Smaller, more efficient data
2. Better performance
3. Easy maintenance
4. Clear and more consistent data
5. Supports reusability
6. Scalability for future growth
Now that we have distributed the data into multiple smaller tables, we need to join the tables. This can be achieved by forming relationships between them, which will act like a bridge for assorted tables. Joining the tables will ease to form a cardinality and use data effectively further for creating the reports. The cardinality, which defines the type of relationship of the data tables can be of four types. These are:
1. One-to-many(1:*)
2. Many -to- One (*:1)
3. One-to- One (1:1)
4. Many-to-many(*:*)
A star schema typically uses one-to-many cardinality, being many to the fact table side. As each dimension contains one unique record for an entity, while the fact table contains many events linked back to that entity. As mentioned earlier, a star schema has two types of components:
Fact tables: To store events or transactions.
Here, many means multiple rows refer to those of customers, products, dates and so on.
Dimension tables: To store unique descriptive information.
Here, one means one row per customer, product, date and so forth.
Now that we have seen how the star schema is structured, lets gather in detail the benefits of adopting a star schema for Power BI data modeling.
1.Simplicity: One of the biggest strengths of a Star Schema is how easy it is to work with. In a flat file, everything sits in one massive table, so hunting for the fields can be overwhelming. A Star Schema fixes that by organizing data into clear dimension tables. Each table groups related attributes together, making it far simpler to navigate the model and quickly find the information one is looking for.
2.Performance: Fewer joins are needed between the tables compared to snowflake schema, which leads to quicker data retrieval. When a dataset is small, a star schema might feel similar to flat table. However, as the data set grows the difference becomes clearer. Data retrieval becomes faster compared to the snowflake schema.
3.Faster Refresh: This point extends to the performance benefit. In Power BI, a star schema can significantly speed up data refreshes. When data is loaded from the source, refresh time often differs between a flat table and a Star Schema, resulting in star schema as an out performer.
4. Straightforward DAX: Another key advantage of a Star Schema is the way it streamlines DAX (Data Analysis Expressions). In a flat file, DAX formulas often become long and complicated because one is forced to manually handle filtering and aggregation. A Star Schema removes that burden by organizing data into proper dimensions and facts, making DAX far cleaner and more readable. Also, this structure lets you rely on Power BI’s built‑in functions without adding unnecessary complexity.
Although building a Star Schema requires thoughtful planning, the effort pays off. Designing fact tables, dimension tables, and their relationships can feel more involved than working with a single flat table, and having more tables naturally adds some complexity. It also introduces multiple relationships that may require additional maintenance. For beginners, concepts like cardinality can feel challenging or overwhelming. In some cases, especially with highly hierarchical data, a snowflake or hybrid schema may work more appropriately.
Even so, the Star Schema stands out by keeping the fact table lean with unique IDs and essential numeric values. It delivers high performance, faster refresh times, and simplified DAX. In the end, despite a few complexities, the Star Schema remains the reliable and performance‑driven foundation for building scalable, efficient, and easy‑to‑maintain Power BI models.


